Statistical Methods for Analyzing Data: Core Techniques Explained With One Worked Case
The majority of statistical errors occur before any calculations are performed: the wrong statistical test is used for a set of data, or some result is reported without its uncertainty. This guide has another approach. It follows one small case, a college which takes a gamble on whether a tutoring programme helps, and uses the primary statistical methods in sequence. Each number has been derived from fictional data marked illustrative, to allow each number to be checked.
Statistical Methods: Description, Inference and Choosing the Right Test
There are two general classes of statistical methods. Descriptive methods summarise the data that you have, including averages, spreads and charts. The inferential methods are used to make inferences about a larger population based on a sample, and they are always accompanied by some degree of uncertainty, hence the presence of confidence intervals and p-value. A P value is the chance of obtaining a result that is at least as significant as your result, when there is no effect. It does not indicate the magnitude or significance of an effect.
Right test is dependent upon type of outcome and collection of data. Table describes typical options, and what to use when the typical assumptions (e.g., that the data is approximately normally distributed) do not apply.
| Outcome and Design | Usual Test | If Assumptions Fail |
| Numeric outcome, two independent groups | Independent t-test | Mann-Whitney U test |
| Numeric outcome, same people measured twice | Paired t-test | Wilcoxon signed-rank test |
| Numeric outcome, three or more groups | One-way ANOVA | Kruskal-Wallis test |
| Two categorical variables | Chi-square test of association | Fisher’s exact test for small counts |
| Two numeric variables | Pearson correlation or regression | Spearman rank correlation |
5 Basic Methods of Statistical Analysis
The five basic methods of statistical analysis can be summarised by the terms: mean, standard deviation, regression, hypothesis testing and the calculation of sample size. They work together on summarising data, measuring spread, modelling relationships, testing claims and planning a study. The ideas developed here are applied in other tests, like the t-test and the chi-square, in later sections.
| Basic Method | Question It Answers | What You Report |
| Mean | What is the typical value? | The average, with the median beside it |
| Standard deviation | How spread out are the values? | SD, and a confidence interval for the mean |
| Regression | How does one variable change with another? | Slope, intercept, R-squared and confidence intervals |
| Hypothesis testing | Is a difference or link larger than chance? | Test statistic, p-value, effect size, confidence interval |
| Sample size determination | How many observations are needed? | Planned n, with the effect, power and error rate assumed |
Statistical Analysis Examples: Analyzing Data in the Tutoring Case
The college has four questions: What are the scores like, do study hours predict scores, does a new method of teaching do better, and is there a difference in satisfaction between two channels of service. A different tool is required for each question. The numbers used are fictional, and the sample size is deliberately small to keep the numbers easy to read.
Stage 1: Describe the Scores
Twelve students score 58, 62, 65, 67, 70, 72, 72, 75, 78, 81, 85 and 90. The mean is 72.9, the median 72, the standard deviation 9.5 and the range 32. A 95% confidence interval for the mean is 66.9 to 78.9, which says the true average for students like these could plausibly lie anywhere in that range. Figure 1 shows how the mean and standard deviation describe a bell-shaped distribution.
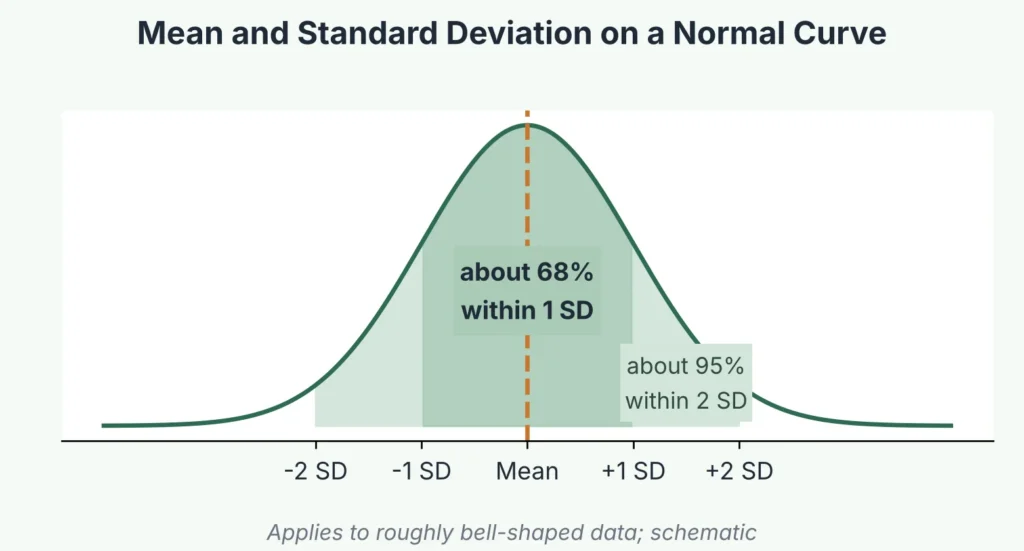
Figure 1: Mean and standard deviation on a normal curve.
Stage 2: Relate Study Hours to Scores
Ten students report study hours from 2 to 11 per week. A simple linear regression gives score = 44.6 + 3.6 x hours. The slope has a 95% confidence interval of 3.2 to 4.1, so each extra hour is linked to roughly three to four more points in this sample. R-squared is 0.98, meaning the line accounts for about 98% of the variation in these ten scores. Figure 2 draws the fitted line with its confidence band.
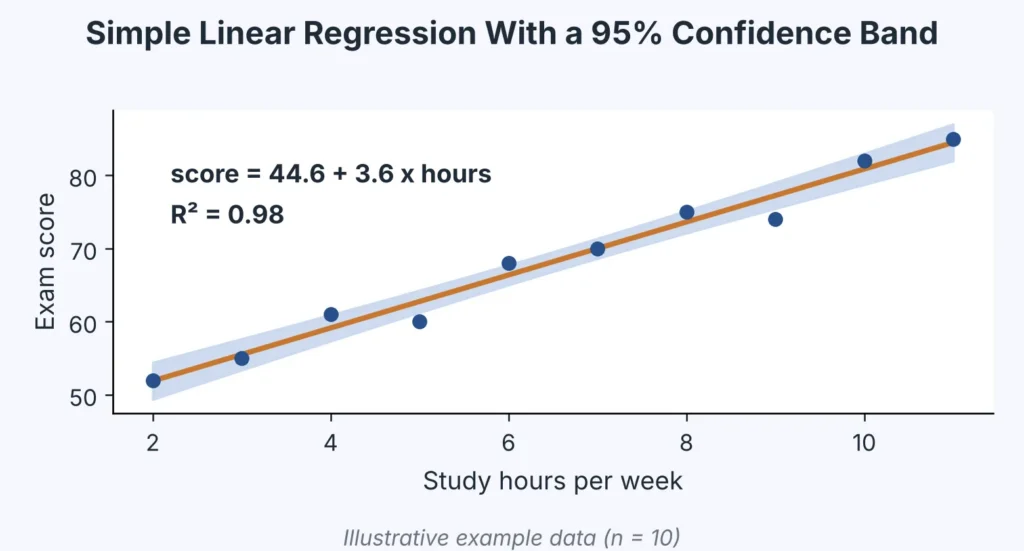
Figure 2: Regression line for study hours and scores, with a 95% confidence band.
Two cautions apply. A regression shows association, not cause, and predictions should stay within the range of hours observed.
Stage 3: Compare Two Teaching Methods
Eight students taught with Method A average 72.3, and eight taught with Method B average 79.4. The hypothesis test follows five steps.
- State the hypotheses. the null hypothesis is that the two means are equal.
- Choose the test. an independent two-sample t-test suits a numeric outcome in two separate groups.
- Set the significance level. 0.05, decided before looking at the data.
- Calculate. t = 4.65 with 14 degrees of freedom, giving p = 0.0004.
- Conclude and report size. Method B scored 7.1 points higher, with a 95% confidence interval of 3.8 to 10.4 and a Cohen’s d of about 2.3.
The p-value says the difference is unlikely to be chance, and the interval and effect size say how large it is. A Welch test, which does not assume equal spreads, gives the same conclusion, and the Mann-Whitney test, which does not assume normality, gives p = 0.002. An effect as large as d = 2.3 is far bigger than most real studies find, because these numbers were invented.
Stage 4: Test an Association Between Categories
About 60 out of 100 students are satisfied with the online channel, while 45 out of 100 students are satisfied of the in-person channel. The difference is 15 percentage points and is in close proximity to the 95% confidence interval of ~1 to 29 points. The results of a chi-square test of association are: Chi Square = 4.51, df = 1, p = 0.034. With a continuity correction the p-value is 0.047. Near 0.05 on both, and the effect is small – about 0.15 – so the honest answer is a small, uncertain difference.
Stage 5: Plan the Sample Size
The team conducts a power calculation before gathering actual data to determine the minimum number of students required in each group to achieve a detection of a 5-point difference between the two methods, with 5% significance level and 80% power, assuming a standard deviation (SD) of 8. Instead of the more common formula for two groups n per group = 2 x (1.96 + 0.84) squared x SD squared / the difference squared, it is commonly used as n per group = 2 x (1.96 + 0.84) squared x SD squared x 2 / the difference squared. That’s 41 students per group approximately, which is about 40.2. A smaller sample may not detect a genuine difference.
The ledger gathers the case in one place.
| Question | Method | Result (Illustrative) | Reading |
| What do the scores look like? | Descriptive statistics | Mean 72.9, SD 9.5, 95% CI 66.9 to 78.9 | Typical student scores about 73, with wide spread |
| Do study hours predict scores? | Linear regression | Slope 3.6 points per hour, 95% CI 3.2 to 4.1, R-squared 0.98 | Strong linear link in this small sample |
| Does Method B beat Method A? | Independent t-test | Difference 7.1 points, 95% CI 3.8 to 10.4, p = 0.0004 | A clear, sizeable difference in this made-up data |
| Does satisfaction differ by channel? | Chi-square test | 60% vs 45%, chi-square 4.51, p = 0.034 | Evidence of a difference, but a small effect |
| How many students are needed? | Sample size calculation | About 41 per group | For a 5-point difference at 80% power |
Statistical Methodology Examples: Pairing Studies With Methods
These statistical methodology examples show how real situations map to methods. The same logic applies whatever the field.
| Study Situation | Method of Statistical Analysis | Why It Fits |
| Satisfaction compared across two service channels | Chi-square test | Both variables are categories |
| Scores of one group before and after training | Paired t-test | The same people are measured twice |
| Sales compared across three regions | One-way ANOVA | Three groups, one numeric outcome |
| Advertising spend and monthly sales | Regression | One variable is used to predict another |
| Customers sorted into similar segments | Cluster analysis | The groups are not known in advance |
| A long survey reduced to a few themes | Factor analysis or PCA | Many related variables are summarised |
Beyond the tests above, multivariate methods such as factor analysis, principal component analysis and cluster analysis handle many variables at once, and they need larger samples and careful interpretation.
How to Choose a Method of Statistical Analysis
- Write the question. decide exactly what you want to know before looking at tools.
- Identify the variables. numeric or categorical, and which is the outcome.
- Note the design. independent groups, repeated measures, or a single sample.
- Check assumptions. look at the data with a chart, and use the alternative test when assumptions fail.
- Report fully. give the test, statistic, p-value, effect size and confidence interval.
Common Mistakes When Analyzing Data
Testing many things and reporting the hits. Each extra test raises the chance of a false positive; plan the tests in advance or adjust for multiple comparisons.
Equating significance with importance. A tiny effect can be significant in a large sample. Report the effect size.
Reading correlation as cause. Association alone does not show that one variable changes the other.
Ignoring assumptions. A t-test or ANOVA on very skewed data with small groups can mislead.
Skipping the chart. A plot often reveals outliers and patterns that numbers hide.
Common software for this work includes SPSS, R, Python, SAS, Stata, Excel and Power BI. The choice of method matters far more than the package.
Simbi Labs’ Statistical Data Analysis Support
Choosing and running the right test is easier with an experienced analyst. Simbi Labs provides statistical data analysis support for research and business studies, and you can discuss your project through the contact page.
Explore Statistical Data Analysis Services
Frequently Asked Questions
1. What are statistical methods?
They are structured ways of summarising data and drawing conclusions from it, split into descriptive methods and inferential methods.
2.What are the 5 basic methods of statistical analysis?
The mean, standard deviation, regression, hypothesis testing and sample size determination.
3.How do I begin analyzing data?
State the question, identify the variable types, chart and summarise the data, and then choose a test that fits the design.
4. What are some statistical analysis examples?
Averaging scores, fitting a regression of scores on study hours, comparing two methods with a t-test, and testing satisfaction by channel with chi-square.
5.What are statistical methodology examples for a study?
A before-and-after training study uses a paired t-test, a three-region comparison uses ANOVA, and customer segmentation uses cluster analysis.
6. How do I choose a method of statistical analysis?
Match it to the question, the data types and the study design, and check that assumptions hold before trusting the result.